Manuscript submitted to ICASSP and rejected.
Abstract
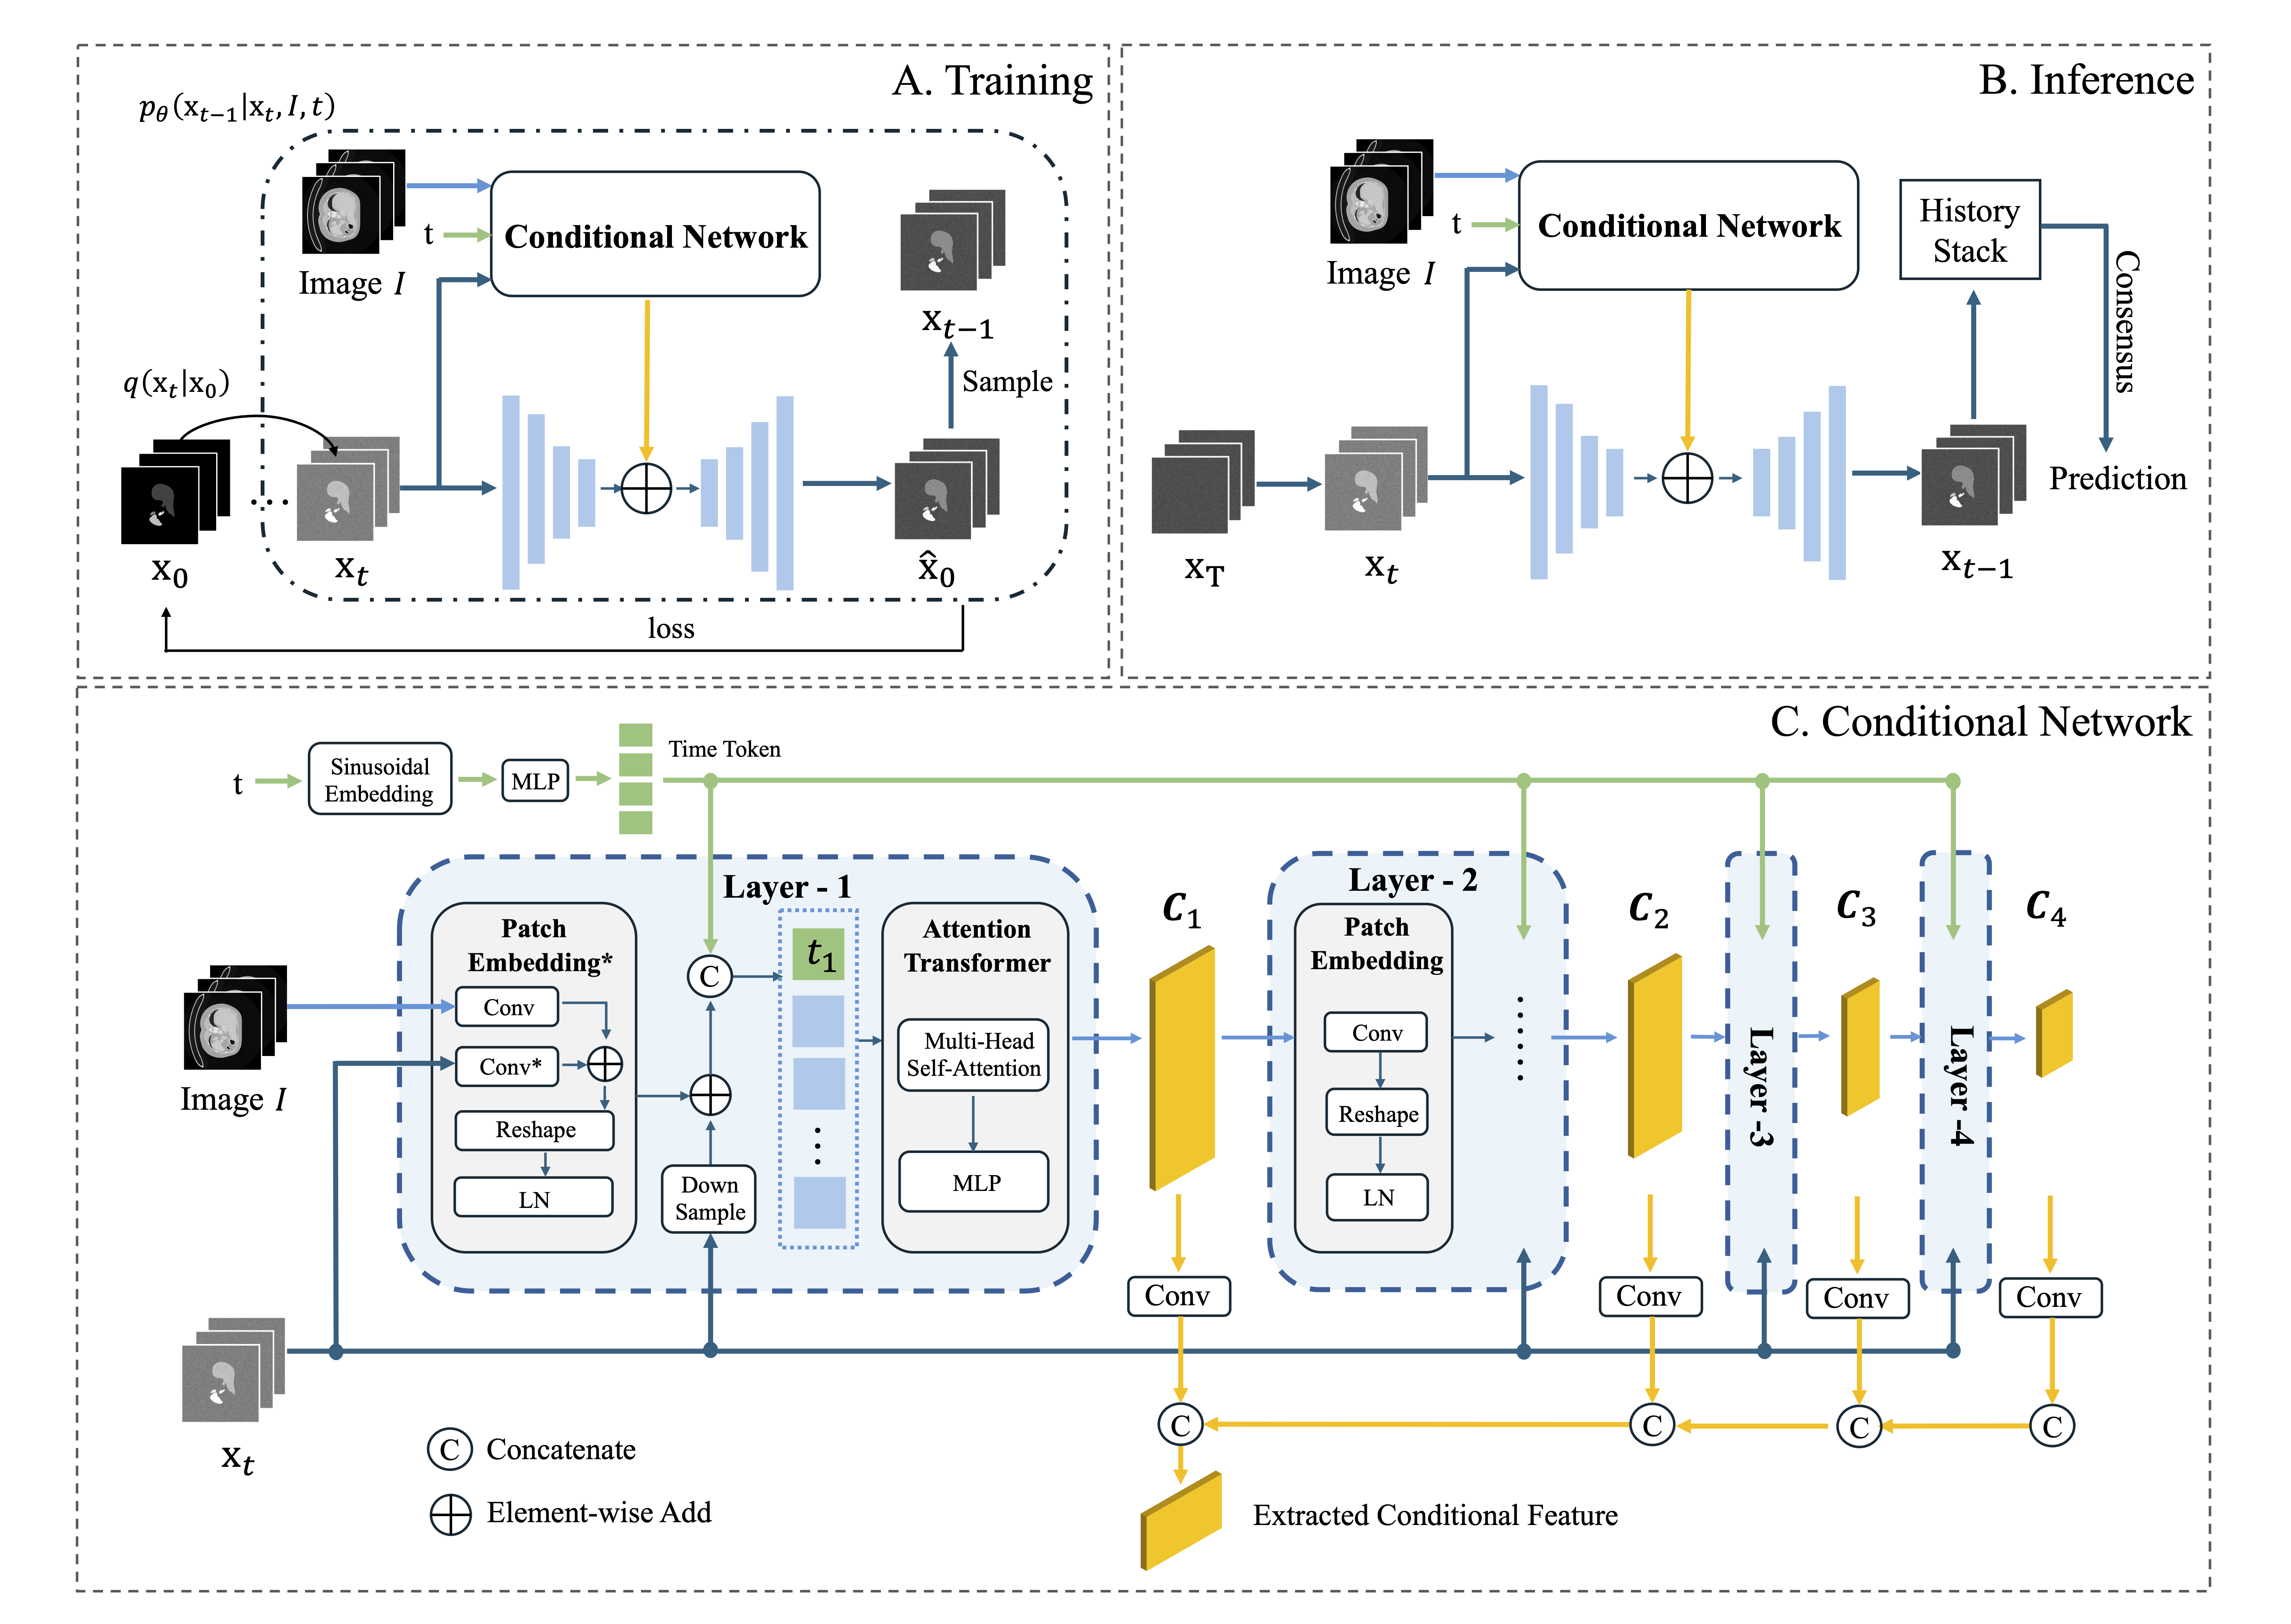
We introduce MedCondDiff, a diffusion-based framework for multi-organ medical image segmentation that is efficient and anatomically grounded. The model conditions the denoising process on semantic priors extracted by a Pyramid Vision Transformer (PVT) backbone, yielding a semantically guided and lightweight diffusion architecture. This design improves robustness while reducing both inference time and VRAM usage compared to conventional diffusion models. Experiments on multi-organ, multi-modality datasets demonstrate that MedCondDiff delivers competitive performance across anatomical regions and imaging modalities, underscoring the potential of semantically guided diffusion models as an effective class of architectures for medical imaging tasks.
Figure 1: MedCondDiff framework. The Conditional Network (‘Adapter’) extracts features and injects them into the denoising network to enhance mask prediction. In the first layer of conditional network, block labeled with $’*’$ processes the noised image $\mathbf{x_t}$ and combines it with regular embedding.